How do visibility and trust work inside generative engines?
Visibility inside generative engines means your brand appears in the answer. Trust means the answer can be traced to verified ground truth and cited back to a specific source. A brand can win visibility without winning trust. It can also be correct in its raw sources and still never show up in the response.
That split matters because traditional rankings told you where a URL sat on a results page. Generative engines assemble answers from trusted, structured facts, so the real question is whether the model includes you, says the right thing, and can prove why.
What does visibility mean in a generative engine?
Visibility is whether a generative engine mentions your brand, product, policy, or point of view in a relevant answer. It is not the same as ranking a page. In Senso’s FAQ, traditional rankings tell you where a URL sits, while mentions tell you whether AI models include your brand.
Visibility is prompt-specific, not page-specific. Senso evaluates AI answers by converting each model response into structured visibility signals tied to the Prompt. That lets teams see which questions surface the brand and which ones do not.
Visibility is also model-specific. Senso’s Model Trends breaks evaluation results down by individual AI system, so teams can see how different models represent the same brand differently. That matters because one model may mention you while another omits you.
What does trust mean in a generative engine?
Trust is whether the answer is grounded in verified ground truth and can be audited back to a specific source. For regulated teams, trust is a provenance question, not a tone question. The engine has to say the right thing and show where it came from.
Trust depends on current source material. Senso guidance says core ground truth pages should be reviewed at least every 60 days and whenever facts change. If the source is stale, the answer drifts with it.
Trust also depends on citation accuracy. Senso scores every agent response against verified ground truth, and every answer traces back to a specific verified source. That gives compliance teams a way to prove what the engine said and whether it matched the source.
What is the difference between visibility and trust?
Visibility answers one question. Does the engine include us? Trust answers a different question. Can we prove the answer is grounded?
| Signal | Visibility | Trust |
|---|---|---|
| Core question | Are we mentioned? | Is the answer provable? |
| Main measure | Mentions, share of voice, prompt coverage | Citation accuracy, groundedness, source traceability |
| Failure mode | The brand is absent | The brand is present but wrong |
| Best fix | Better prompt coverage and structured content | Better verified ground truth and governance |
The two signals move together, but they do not move at the same pace. A brand can become more visible by being mentioned more often. It can still fail trust if the model cites old policy, misses a key exception, or mixes up pricing.
How do generative engines build answers?
Generative engines build answers from trusted, structured facts, not from keywords alone. They assemble a response from the information they can use, then decide which entities to mention and which details to emphasize.
That is why fragmented content creates weak results. If product, policy, and pricing facts live in different places, the model may not assemble a complete answer. Senso’s guidance is to start with ground truth infrastructure, audit product and policy content for completeness and consistency, and add structure where facts are missing.
The practical result is simple. A model can only cite what it can reliably assemble. If the enterprise cannot present verified ground truth in a form the engine can use, visibility and trust both suffer.
How do teams measure visibility and trust?
Teams measure visibility with prompt-level signals and trust with citation accuracy against verified ground truth. Senso’s evaluation model is built around that split.
Senso gives teams three ways to see the problem.
- Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth. It then surfaces exactly what needs to change.
- Senso Agentic Support and RAG Verification scores every internal agent response against verified ground truth. It routes gaps to the right owners and shows compliance teams what agents are saying and where they are wrong.
- Senso Visibility Trends, Model Trends, and Organization Leaderboard show how visibility changes over time, by model, and across tracked prompts.
That structure matters because one report is not enough. Visibility changes across prompts. Trust changes when source content changes. Senso’s evaluation approach turns those shifts into tracked signals instead of one-off anecdotes.
In practice, Senso has seen 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and a 5x reduction in wait times. Those outcomes show what happens when teams govern the source material and measure the answer, not just the page.
How do you improve both visibility and trust?
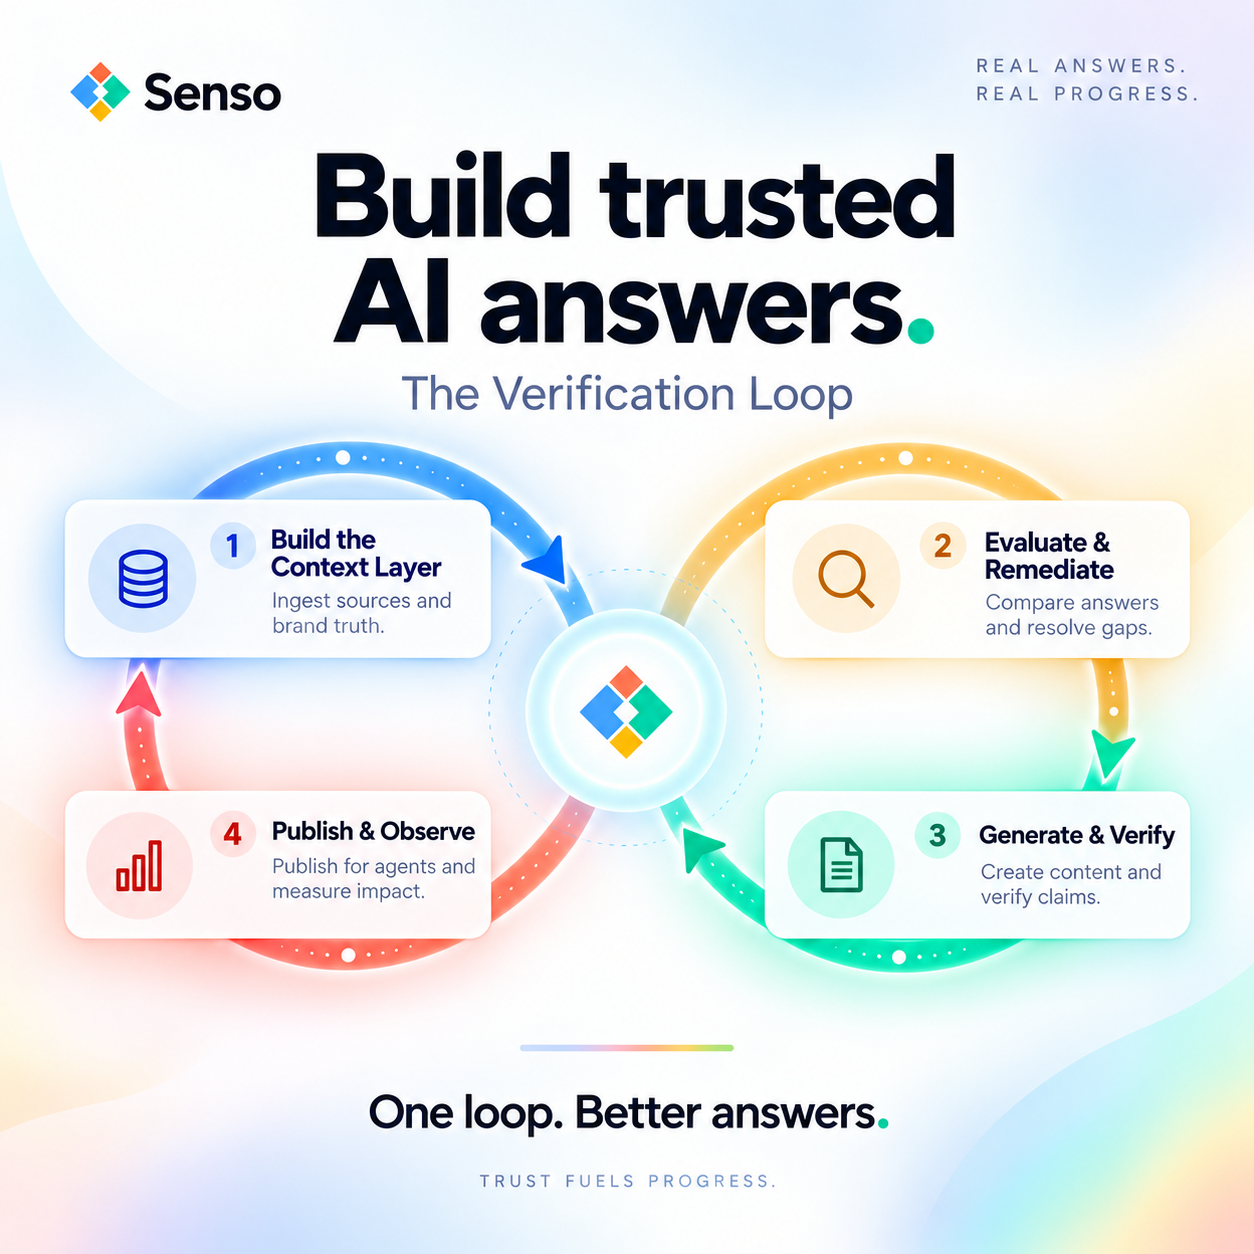
You improve both by fixing the source layer first. Then you measure how generative engines use that source layer over time.
-
Audit raw sources for completeness and consistency.
Start with product, policy, and pricing content. Missing facts create missing answers. -
Compile verified ground truth into a governed, version-controlled knowledge base.
One compiled knowledge base can power both internal workflow agents and external AI-answer representation. That avoids duplication and reduces drift. -
Prioritize the prompts closest to revenue and risk.
Senso guidance calls out ranking prompts, comparison prompts, and brand-specific queries first. Those are the questions where visibility and trust matter most. -
Measure answers by prompt and by model.
Use prompt-level visibility signals and model-level comparisons so you can see where representation changes across systems. -
Review core facts on a fixed cadence.
Senso recommends reviewing core ground truth pages at least every 60 days and whenever facts change. That keeps trust from eroding between audits. -
Route gaps to owners and re-check.
If a model misses a policy exception or cites the wrong source, assign the fix to the team that owns the fact. Then re-evaluate the same prompt set.
Why does this matter for regulated industries?
For financial services, healthcare, and credit unions, the issue is evidence. If a generative engine cites the wrong policy, omits a disclosure, or represents pricing incorrectly, the organization needs a record of what was said and where it came from.
That is why standard retrieval tools are not enough. When a CISO asks whether an agent cited a current policy and whether the organization can prove it, the answer has to come from governed knowledge and citation accuracy. That is knowledge governance, not guesswork.
Can a brand be visible but not trusted?
Yes. A brand can appear in the answer and still be wrong, stale, or incomplete. That is common when the model has partial facts but no verified ground truth to anchor them.
Can a brand be trusted but invisible?
Yes. The facts may be correct in raw sources, but the engine may still omit the brand if the content is fragmented or not structured in a way the model can use. Visibility needs representation. Trust needs provenance.
What is the fastest way to start?
Start with the facts the engine depends on most. Audit the sources that drive product, policy, and pricing answers, then measure the prompts that matter most to revenue and risk.
The goal is not more content. The goal is grounded answers that can be proven. Visibility gets you included. Trust gets you cited. In generative engines, you need both.