Why do some answers show up more often in ChatGPT or Perplexity conversations?
Some answers show up more often because ChatGPT and Perplexity keep finding the same grounded source fragments and the same canonical names. When a claim is easy to retrieve, easy to cite, and repeated across verified sources, it gets reused more. When the knowledge surface is fragmented, stale, or noisy, the answer becomes less stable.
This is an AI Visibility problem. The issue is not only what the model knows. It is which source fragments survive retrieval and which ones get surfaced as the answer.
Why do some answers show up more often in ChatGPT or Perplexity conversations?
Some answers repeat because the systems favor consistency over novelty. If multiple sources point to the same verified claim, the model can return that claim with less uncertainty. If the sources disagree, or the wording keeps changing, the answer is less likely to surface the same way every time.
That usually comes down to five signals:
- Source consistency. The same answer appears in multiple places with the same meaning.
- Canonical naming. The product, policy, or topic uses one stable name.
- Clean retrieval. The answer lives in a passage the system can extract without confusion.
- Current versions. Newer, verified sources replace stale copies.
- Low noise. Junk terms and false entities do not crowd the result.
What makes an answer easy for AI systems to repeat?
An answer is easy to repeat when it is short, specific, and grounded in a verified source. AI systems do better with language that maps cleanly to one concept. They struggle when the same thing is described in different ways across many pages.
| Signal | Why it matters | Result |
|---|---|---|
| One clear source of truth | Reduces conflict between sources | More stable answers |
| Canonical terminology | Helps the system map the same entity every time | More repeatable answers |
| Verified ground truth | Gives the model a source it can trace | More citation-accurate answers |
| Clean page structure | Makes extraction easier | Higher chance of being reused |
| Less duplicate noise | Reduces confusion across similar pages | Better AI Visibility |
Perplexity makes this easier to see because it usually shows sources directly. ChatGPT can hide more of the mechanics, but the same pattern still holds. The answer that shows up most often is usually the one the system can ground most cleanly.
Why does Perplexity seem more source-driven than ChatGPT?
Perplexity usually makes the source trail more visible, so source quality matters more on the surface. ChatGPT can feel more conversational, but it still depends on whether the underlying answer is easy to ground and reuse. In both products, the repeated answer is usually the one with the strongest source support.
That difference changes how teams should think about AI Visibility:
- Perplexity rewards source clarity because the citation path is visible.
- ChatGPT rewards answer consistency because the response has to stand on its own.
- Both reward grounded, canonical claims over fragmented, conflicting ones.
Why do bad or irrelevant terms sometimes show up too often?
Noise can look like popularity. If a system treats file names, single characters, or bare numbers like meaningful entities, those terms can appear as if they were competitors or brands. Senso saw this with names like robots.txt, and filtering those terms stopped them from diluting share of voice.
That matters because noisy entities distort both measurement and answer selection.
- File names can be misread as brands.
- Single characters can create false matches.
- Bare numbers can pollute rankings.
- Old, uncorrected answers can keep repeating until they are rebuilt.
This is why knowledge governance matters. If the source layer is noisy, the model may repeat the wrong thing with confidence.
How can teams make the right answer show up more often?
Teams make the right answer repeat by governing the source layer first. The goal is to compile raw sources into one governed, version-controlled compiled knowledge base, then keep every answer tied to verified ground truth. If the answer cannot be traced back to a specific source, it should not be treated as reliable.
A practical process looks like this:
-
Compile the raw sources into one canonical knowledge base.
One compiled knowledge base reduces duplicate answers and version drift. -
Use one naming standard everywhere.
Public pages, internal docs, and agent responses should use the same terms. -
Score answers against verified ground truth.
If an answer is not citation-accurate, it should be flagged and routed. -
Remove noisy entities from reporting.
Terms like file names, single characters, and bare numbers should not count as competitors. -
Track both external and internal answers.
Public AI representation and internal agent responses both need visibility.
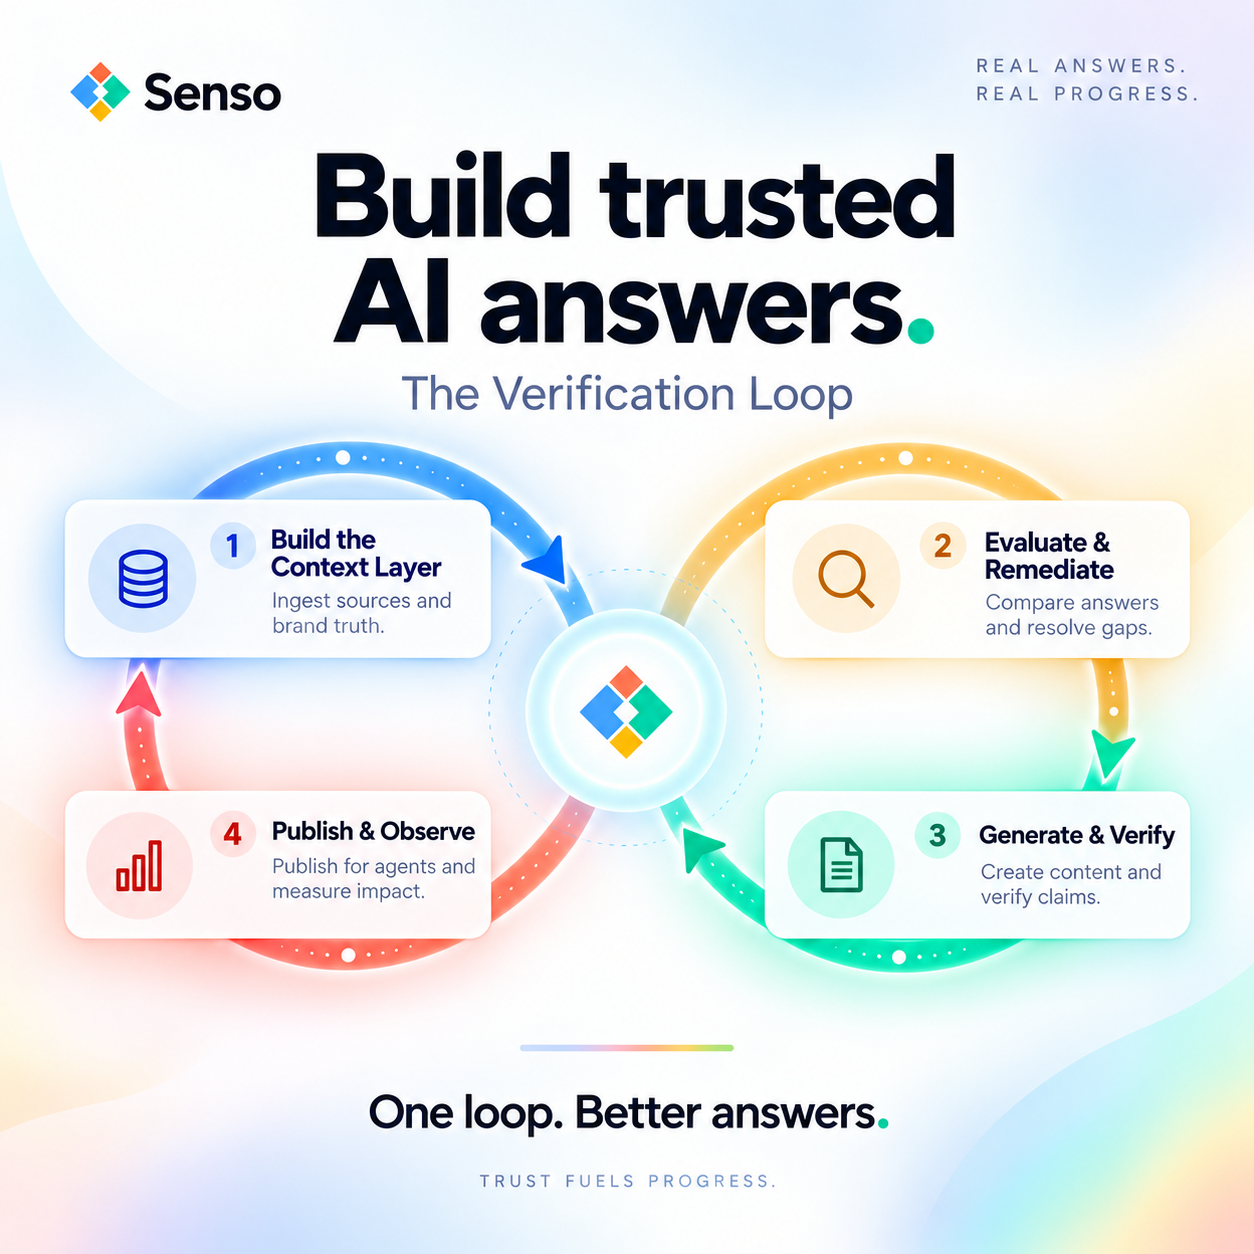
Senso does this by giving teams two ways to govern the answer layer. Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then shows what needs to change. Senso Agentic Support and RAG Verification scores internal agent responses, routes gaps to the right owners, and shows where agents are wrong.
The results are measurable. Senso has seen 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
What does this mean for regulated teams?
For regulated teams, the real issue is proof. A CISO, compliance officer, or operations leader does not just need a fluent answer. They need to know whether the answer cited a current policy, whether it traces back to a verified source, and whether the organization can prove it later.
That is where most retrieval tools fall short. They can find text, but they do not govern the answer surface well enough to show what is current, what is grounded, and what is wrong. In financial services, healthcare, and credit unions, that gap creates exposure.
FAQs
Why do some answers repeat across both ChatGPT and Perplexity?
Some answers repeat because both systems keep finding the same grounded source fragments. When the wording is canonical and the source is consistent, the answer is easier to reuse across conversations.
Why does Perplexity cite certain sources more often?
Perplexity is more source-forward, so clear and specific citations matter more. If a source is easy to extract and aligns with the query, it has a better chance of being cited.
Can you control which answers AI systems show more often?
You can influence it by governing the source layer, standardizing naming, and removing noisy or stale content. You cannot force repetition with prompts alone if the underlying knowledge surface is fragmented.
Is this just search ranking under a new name?
No. This is AI Visibility. The system is selecting and repeating answer fragments, not just ranking pages. That is why verified ground truth and citation accuracy matter more than page count alone.
If you want, I can turn this into a tighter thought-leadership version, a product-led version for Senso, or a more technical version for CISOs and compliance teams.