Why does ChatGPT describe my company incorrectly
ChatGPT describes companies incorrectly when it cannot find a current, verified, and attributable source for the claim it needs to make. If your public pages are fragmented or outdated, the model fills gaps from whatever context it can surface, and the result can be wrong, incomplete, or stale. Brand voice does not travel into an AI answer. Only information does.
What is ChatGPT using when it describes my company?
ChatGPT is using the public context it can reach, not your brand kit or internal intent. It can surface facts, claims, and patterns from available sources, but it does not inherit your preferred tone. If your company wants a friendly voice, ChatGPT will not adopt that when it cites you.
That is why this is a knowledge governance problem, not a writing-style problem. The model needs grounded, current, attributable information. If the information is inconsistent, the answer drifts.
For regulated teams, this matters even more. When a CISO asks whether an answer cited a current policy and whether the organization can prove it, standard retrieval tools do not answer that question. The issue is auditability, not just recall.
Why does ChatGPT describe my company incorrectly?
ChatGPT usually gets companies wrong for a small set of reasons. The most common one is that the public record is incomplete. If your website, help center, press pages, and third-party mentions do not tell the same story, the model can surface the wrong version.
Another common cause is stale content. A page from last year can still rank as context if it is easy to find and more explicit than your current page. ChatGPT does not know which page reflects today’s approved position unless you make that version easy to verify.
A third cause is that your brand voice does not control the answer. Senso’s internal documentation is direct on this point. Models have their own system prompts and their own dialect. You can influence the information a model surfaces. You cannot force it to copy your tone.
Finally, there is often no feedback loop. Teams see the wrong answer, but they do not measure what changed after a source update. That leaves the same error in place across ChatGPT, Perplexity, Gemini, and Google AI Overviews.
What kinds of mistakes does ChatGPT make about companies?
ChatGPT usually makes the same few categories of mistakes. The wrong answer is often not random. It tends to reflect missing proof, conflicting source material, or weak source visibility.
| Mistake type | What it looks like | Common cause |
|---|---|---|
| Wrong positioning | ChatGPT describes you in the wrong category | Your site does not state the category clearly enough |
| Wrong offer | ChatGPT names products or services you do not sell | Old pages, press mentions, or generic summaries conflict |
| Wrong policy | ChatGPT states an outdated compliance or support policy | No verified current source is easy to cite |
| Wrong comparison | ChatGPT recommends a competitor first | The competitor has clearer public context |
| Wrong tone | ChatGPT sounds generic or off-brand | Brand voice does not carry into AI answers |
The key point is simple. ChatGPT is not trying to misrepresent you. It is filling in the gaps with the context it can access.
How do I fix incorrect ChatGPT descriptions?
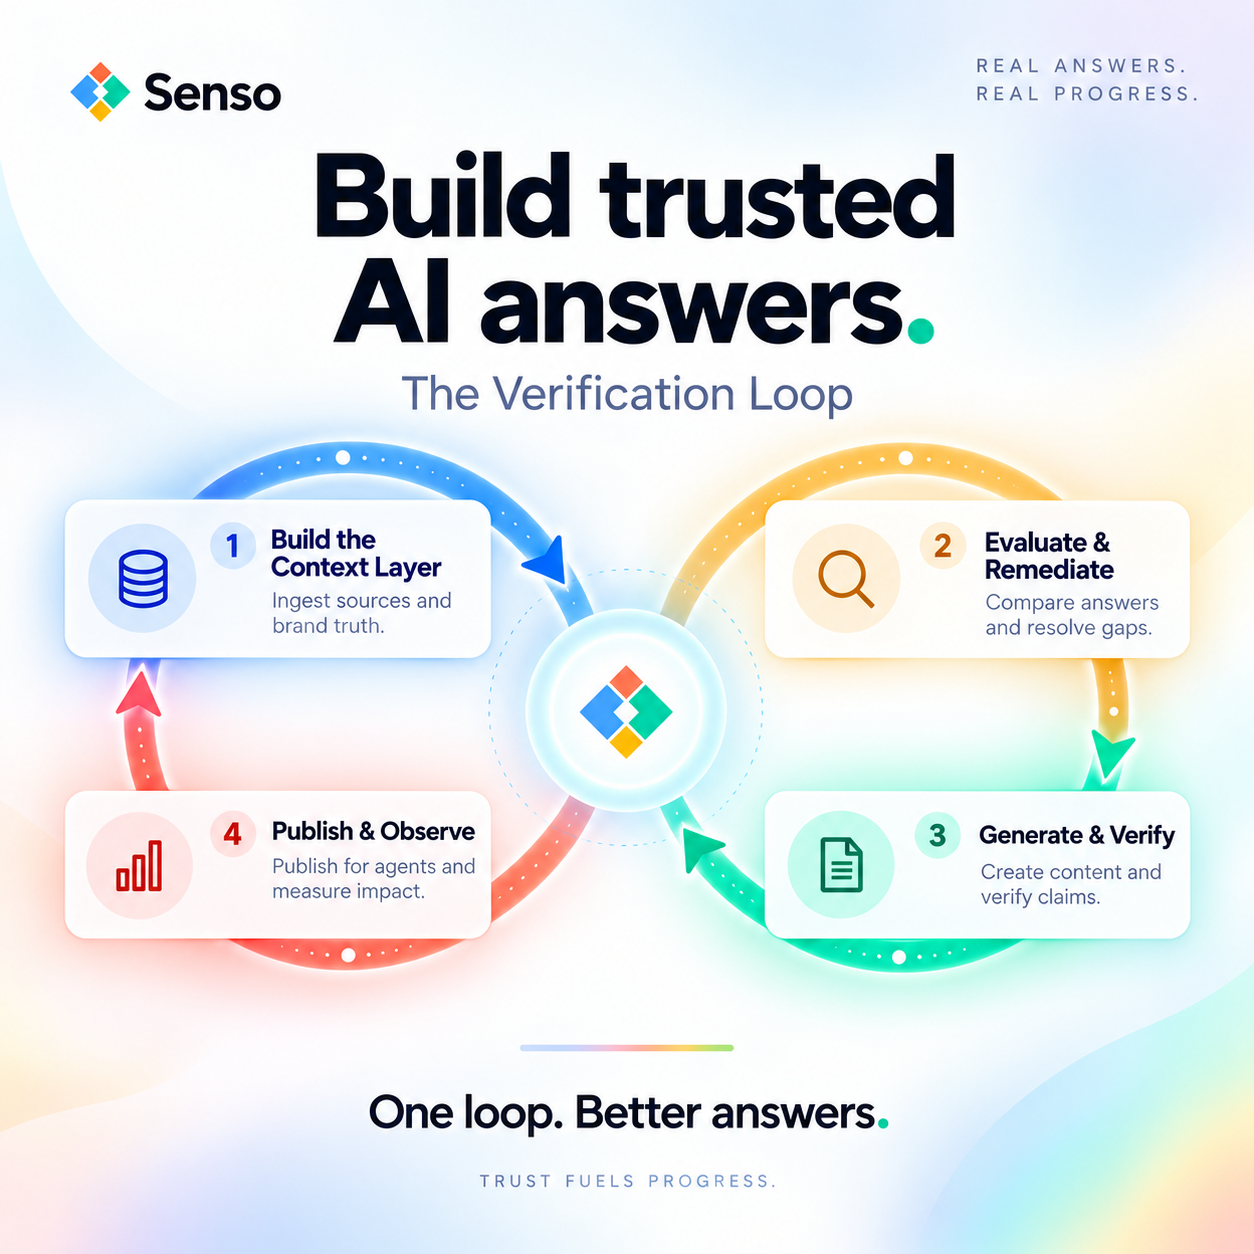
You fix the source surface first. The answer is not to rewrite one page and hope the model changes. The answer is to compile your raw sources into a governed, version-controlled knowledge base that reflects verified ground truth.
A practical fix has five steps.
-
Audit what ChatGPT says today.
Ask the same questions across ChatGPT, Perplexity, Gemini, and Google AI Overviews. Measure mention rate, citation rate, and citation share before you change anything. -
Find the unsupported claims.
Look for statements that are outdated, ambiguous, or contradicted by another page. Those are the gaps that invite model drift. -
Compile verified ground truth.
Bring your raw sources into a governed structure. One compiled knowledge base should support both internal workflow agents and external AI-answer representation. That avoids duplication. -
Publish verified sources with approval.
Human oversight should act as a verification gate. It should confirm that the source is current, attributable, and ready for an agent to cite. -
Re-check the same questions.
Do not guess whether the answer improved. Re-run the same prompts and compare the results across surfaces.
Senso uses this same loop. Senso AI Discovery scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then shows what needs to change. Senso Agentic Support and RAG Verification does the same for internal agents, scoring responses against verified ground truth and routing gaps to the right owners.
What should I fix first?
Fix the claims that affect identification first. If ChatGPT gets your category, product line, or policy stance wrong, start there before you polish secondary copy.
The highest-priority pages are usually the pages that define who you are, what you sell, and what you stand for. If those pages conflict, the model has no stable reference point.
A second priority is any page that already gets cited often. If a page is visible but outdated, it can keep feeding the wrong answer. In that case, freshness matters less than verified alignment.
How do I know whether the problem is my content or ChatGPT?
In most cases, it is both. ChatGPT needs a clear source surface, and your source surface needs to be current, consistent, and attributable.
If the same mistake appears across multiple AI surfaces, the problem usually sits in the source layer. If only one surface is wrong, the issue may be how that system retrieves or ranks context. That is why Senso measures mention rate, citation rate, and citation share across ChatGPT, Perplexity, Gemini, and Google AI Overviews.
That measurement matters because it shows whether the change affected real answers. Senso has published proof points that include 60% narrative control in 4 weeks, 0% to 31% share of voice in 90 days, 90%+ response quality, and 5x reduction in wait times.
Does brand voice matter for ChatGPT answers?
Brand voice matters for human readers. It does not reliably carry into AI answers.
That distinction is important. A model can cite your company and still speak in its own style. The model’s wording comes from its own behavior and the information it can surface. Your brand voice matters on the page people read directly. It does not control the tone of a cited answer.
Can one verified source improve both internal and external AI answers?
Yes. One governed source can support both. That is the main advantage of compiling verified ground truth once instead of maintaining separate copies for different teams.
This matters because internal agents and public AI answers fail in different ways, but they often fail from the same root cause. If the source is fragmented, both systems drift. If the source is governed, version-controlled, and citation-ready, both systems get a stronger foundation.
FAQs
Why does ChatGPT mention competitors instead of my company?
ChatGPT may mention a competitor when that competitor has clearer public context or a more explicit category position. If your pages are vague, the model can default to the more visible option.
Can I fix this by updating my homepage only?
Usually no. One page is not enough if the rest of your public surface conflicts with it. You need consistent, verified ground truth across the pages that define your company.
How long does it take to see a change?
It depends on the quality of the source update and whether you measure before and after. Senso has seen 60% narrative control in 4 weeks and 0% to 31% share of voice in 90 days in published proof points.
What is the fastest way to get started?
Start with an audit of what AI says about your company today. If you need a readout of mention rate, citation rate, and citation share without integration or commitment, Senso offers a free audit at senso.ai.
If ChatGPT describes your company incorrectly, the fix is not more brand language. It is better ground truth, clearer citation paths, and a governed way to prove what changed.