What are self-evolving agents?
Self-evolving agents are AI agents that improve their behavior over time by using feedback, outcomes, and verified ground truth. In enterprise use, that does not mean free-form self-modification. It means controlled updates that keep answers grounded, citation-accurate, and auditable.
They matter because agents already answer questions about products, policies, and pricing. If the knowledge behind those answers is fragmented or stale, the agent can repeat errors, misstate policy, or expose the business to risk.
How are they different from standard agents?
The difference is about change control. A static agent stays mostly fixed. A self-evolving agent changes from feedback and evaluation. Rule-based automation changes only when a person edits the rules.
| Type | What changes over time | Best fit | Main risk |
|---|---|---|---|
| Static agent | Prompt and source set stay fixed | Stable tasks with low change | Staleness |
| Self-evolving agent | Behavior changes from feedback, evaluation, and corrected sources | Knowledge-heavy workflows that need continual improvement | Drift without governance |
| Rule-based automation | Predefined rules stay fixed | Narrow, repetitive tasks | Brittleness on exceptions |
A self-evolving agent is useful when the job changes often enough that fixed prompts and static retrieval stop keeping up. It is not useful when the task is simple and the rules rarely change.
How do self-evolving agents improve over time?
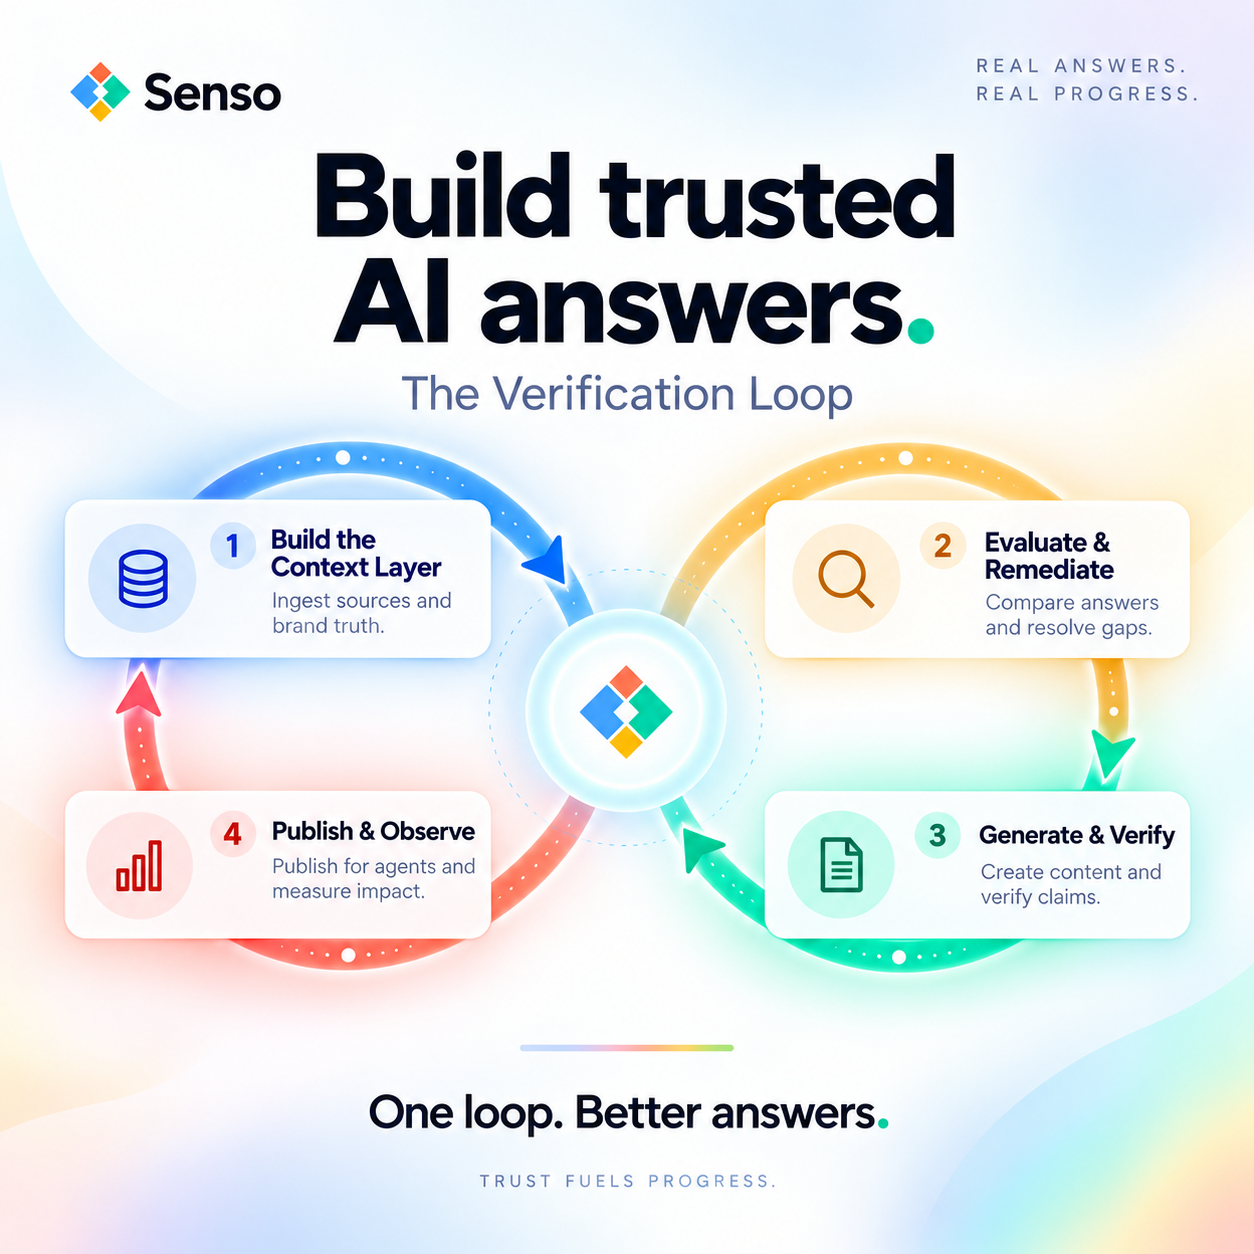
They improve through a governed feedback loop. The agent answers a question, the system scores the answer against verified ground truth, and the gaps route to the right owner. Approved corrections then update the knowledge base, prompts, or routing rules.
- Ingest raw sources into a compiled knowledge base.
- Query the compiled knowledge base when the agent answers.
- Score each response for citation accuracy against verified ground truth.
- Route failures to the right owner.
- Update the source of record, then re-run the evaluation.
- Use the next round of responses to confirm the change worked.
That is the safe version of self-evolution. The agent improves because the organization improved the source of record, not because the model started rewriting itself without control.
What do they need to stay reliable?
They need governance. A self-evolving agent should never learn from unverified answers or from sources that no one can trace. The safest model is one compiled knowledge base, one version of ground truth, and one audit trail for every answer.
- A governed, version-controlled compiled knowledge base.
- Source tracing for every response.
- Human review for policy, pricing, and regulated content.
- Clear ownership for gaps and exceptions.
- Quality metrics that measure citation accuracy and response quality, not just task completion.
Senso, backed by Y Combinator (W24), is built around that model. Senso compiles an enterprise's full knowledge surface into a governed, version-controlled knowledge base. In deployment, Senso reports 90%+ response quality and 5x reduction in wait times. For external AI Visibility, Senso reports 60% narrative control in 4 weeks and 0% to 31% share of voice in 90 days.
Those outcomes matter because they show what happens when the feedback loop is grounded in verified ground truth. The agent improves, and the organization can prove why.
Where do self-evolving agents help most?
They help most where the answer surface changes often and the cost of a wrong answer is high. That includes support, policy Q&A, regulated workflows, and public brand responses.
- Internal support and operations. Self-evolving agents reduce repeat questions when answers are stored in a governed knowledge surface.
- Compliance and policy questions. Self-evolving agents need citation accuracy when staff ask about current rules or approved wording.
- External AI Visibility. Self-evolving agents shape how AI models represent the organization in public answers.
- Escalation workflows. Self-evolving agents route gaps to the right owner instead of guessing.
Senso AI Discovery is built for external representation. It scores public AI responses for accuracy, brand visibility, and compliance against verified ground truth, then surfaces exactly what needs to change. No integration is required.
Senso Agentic Support and RAG Verification is built for internal use. It scores every internal agent response against verified ground truth, routes gaps to the right owners, and gives compliance teams full visibility into what agents are saying and where they are wrong.
What can go wrong without governance?
They can drift. They can also lock in the wrong lesson if the feedback loop uses stale raw sources or unverified corrections. In regulated teams, that creates an audit problem because the organization cannot prove why the answer changed.
- Stale policy becomes the new default.
- Repeated errors scale quickly.
- The system sounds confident without being grounded.
- Teams lose the trail from answer to source.
- Compliance cannot prove current policy use.
This is why self-evolving agents are a knowledge governance problem, not just an automation problem. The risk is not that the agent changes. The risk is that it changes in the wrong direction.
When should a team use self-evolving agents?
Use them when the work changes often, the answer matters, and someone must be able to prove where the answer came from. If the task is narrow and stable, simpler automation may be enough.
They are a strong fit when:
- The agent answers questions about products, policies, or pricing.
- The work spans multiple teams or source systems.
- You need auditability for regulated or customer-facing answers.
- You want the system to improve without losing control.
They are a poor fit when the process is fixed, the content rarely changes, or the team cannot maintain a source of truth.
Are self-evolving agents the same as autonomous agents?
No. Autonomy means the agent can act without waiting for a person. Self-evolving means the agent improves over time. A system can be autonomous and still stay fixed. A system can also evolve while still asking for human approval on sensitive changes.
Do self-evolving agents replace human review?
No. They reduce manual work, but they do not remove accountability. Human owners still need to approve policy changes, resolve edge cases, and review high-risk answers.
How do you know one is getting better?
Measure citation accuracy, response quality, and wait time. Those metrics show whether the agent is improving the right behavior. Senso reports 90%+ response quality and a 5x reduction in wait times in governed deployments.
How do self-evolving agents affect AI Visibility?
They shape how AI models represent your organization in public answers. If the knowledge base is governed, those answers stay grounded in verified ground truth. If the knowledge base is fragmented, the model can misstate policy, product details, or positioning.
The useful version of a self-evolving agent is not a system that changes itself blindly. It is a governed system that learns from verified ground truth, keeps a source trail, and improves the next answer without losing accountability.